
The best GPU for local LLMs and AI is the one with enough VRAM for the models you actually run, and then the most memory bandwidth you can afford within that tier. In October 2026 that means the RTX 5070 Ti is the best 16GB card, a used RTX 3090 or RTX 4090 is the best route to 24GB, the RTX 5090 is the fastest 32GB card with AMD’s Radeon AI PRO R9700 as the budget 32GB option, and the RTX PRO 6000 Blackwell is the pick if you need 96GB on one card. This guide is organized by VRAM tier, so you can start from the models you want and work back to the card.
- Verdict at a glance
- How much VRAM do local LLMs need?
- Why bandwidth decides speed within a tier
- Comparison table
- 16GB tier: the starting point
- 24GB tier: the enthusiast sweet spot
- 32GB tier: room for bigger models and long context
- 48GB to 96GB tier: 70B and beyond on one card
- When a GPU is not the answer
- How to choose
- Power, cooling and the rest of the build
- Setup tips
- Common mistakes
- Products Mentioned in This Guide
- How we compared
- Sources
- Frequently Asked Questions
Quick answer: For most people in 2026, the best gpu for local llms by vram tier (2026) is the 7B to 8B — our #1 rated choice. See the full ranked comparison, alternatives and buying advice below.
Verdict at a glance
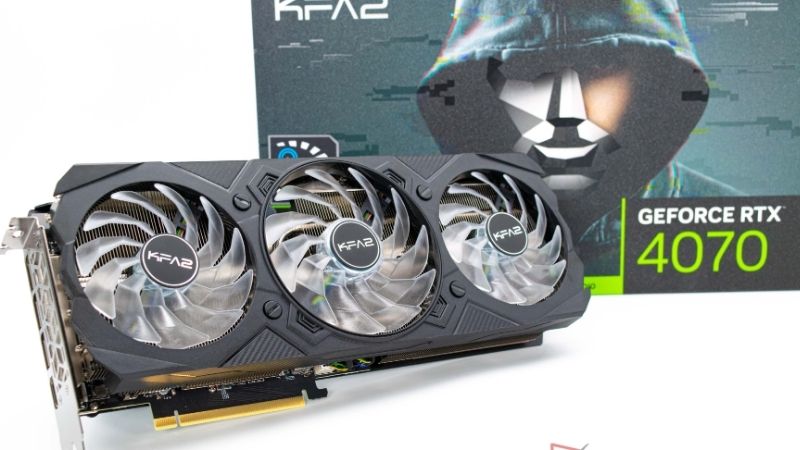
- Best overall: GeForce RTX 5090 (32GB, 1,792 GB/s). Fastest consumer card for any model that fits.
- Best value: GeForce RTX 5070 Ti (16GB, 896 GB/s). Runs 14B models at 58 to 73 tokens per second in published results.
- Best budget 16GB: GeForce RTX 5060 Ti 16GB. Half the bandwidth of the 5070 Ti, but the cheapest 16GB NVIDIA card.
- Best 24GB: used RTX 3090, or an RTX 4090 if you can find one.
- Best budget 32GB: AMD Radeon AI PRO R9700. About two-thirds of a 5090’s generation speed at a much lower tier.
- Best for 70B-plus models on one card: NVIDIA RTX PRO 6000 Blackwell (96GB).
- Best Intel option: Arc Pro B60 24GB, for Linux users comfortable with Intel’s software stack.
How much VRAM do local LLMs need?
Model weights take up most of the memory. A useful rule: at 4-bit quantization (Q4_K_M in GGUF terms), each billion parameters needs a little over half a gigabyte. Then add memory for the context window, called the KV cache, which grows as conversations get longer.
| Model size | Approximate 4-bit weights | Minimum comfortable VRAM | Examples |
|---|---|---|---|
| 7B to 8B | About 5GB | 8GB to 12GB | Llama 3.1 8B, Qwen 8B-class |
| 14B | About 9GB | 12GB to 16GB | Qwen 14B-class |
| 20B MoE | About 13GB | 16GB | gpt-oss-20b, designed by OpenAI to run within 16GB |
| 27B to 32B | About 17GB to 20GB | 24GB, ideally 32GB | Qwen and Gemma 27B to 32B-class |
| 70B | About 39GB to 43GB | 48GB or more | Llama 3.3 70B |
| 120B MoE | About 60GB-plus | 80GB to 96GB, or unified memory | gpt-oss-120b |
The 70B figure comes from published guidance noting a Q4_K_M 70B model needs roughly 39 to 43GB for weights alone. That is why no single consumer card runs 70B at 4-bit without compromises.
Why bandwidth decides speed within a tier
Once a model fits, generation speed tracks memory bandwidth because each new token requires streaming the active weights from VRAM. That is why the RTX 5070 Ti and RTX 5060 Ti 16GB, with identical capacity, perform so differently: 896 GB/s versus 448 GB/s. Compute matters most for reading long prompts, where NVIDIA’s tensor cores give it a clear lead over AMD and Intel cards with similar bandwidth.
Comparison table
| GPU | VRAM | Bandwidth | Board power | Published generation result | Source |
|---|---|---|---|---|---|
| RTX PRO 6000 Blackwell | 96GB GDDR7 | About 1,792 GB/s | 600W | 215 tok/s, gpt-oss-20b in Ollama | LMSYS |
| RTX 5090 | 32GB GDDR7 | 1,792 GB/s | 575W | 194 tok/s, 35B MoE at Q4; 159 tok/s, 8B at Q8_0 | llama.cpp discussion #19890; OpenBenchmarking.org |
| Radeon AI PRO R9700 | 32GB GDDR6 | 640 GB/s | 300W | 127 tok/s, 35B MoE at Q4 | llama.cpp discussion #19890 |
| RTX 4090 | 24GB GDDR6X | 1,008 GB/s | 450W | 101 tok/s, 8B at Q8_0 | OpenBenchmarking.org |
| RTX 3090 (used) | 24GB GDDR6X | 936 GB/s | 350W | 91 tok/s, 8B at Q8_0 | OpenBenchmarking.org |
| Arc Pro B60 | 24GB GDDR6 | 456 GB/s | Varies by board | Single-card measurements scarce | StorageReview, Level1Techs owners |
| RTX 5070 Ti | 16GB GDDR7 | 896 GB/s | 300W | 73.2 tok/s, 14B at Q4_K_M | ComputingForGeeks |
| RX 9070 XT | 16GB GDDR6 | 640 GB/s | 304W | 54.3 tok/s, 14B at Q4_K_M (HIP) | llama.cpp issue tracker |
| RTX 5060 Ti 16GB | 16GB GDDR7 | 448 GB/s | 180W | 42.3 tok/s, 14B at Q4_K_M | ComputingForGeeks |
Results come from different software builds, models and settings. Use them to compare tiers, not as exact head-to-head figures.
16GB tier: the starting point
Sixteen gigabytes runs every 7B to 14B model comfortably, plus gpt-oss-20b. For most people experimenting with local chat, coding help and document Q&A, this tier covers daily use.
RTX 5070 Ti: best value
The 5070 Ti pairs 16GB with 896 GB/s of GDDR7. ComputingForGeeks measured Qwen2.5 14B at 73.2 tokens per second versus 42.3 on the RTX 5060 Ti 16GB, and found the 5070 Ti 1.66 to 1.85 times faster across models. Hardware Corner’s ranking at a 16K context shows 58 tokens per second on Qwen3 14B. ComputingForGeeks also calculated that the 5070 Ti costs less per token per second than the 5060 Ti at September 2026 pricing.
Reasons to pick: excellent speed for 14B-class models; full CUDA support; great gaming card too.
Reasons to skip: 16GB ceiling rules out 27B-plus models at good quality.
The catch: the RTX 5080 adds only a little bandwidth (960 GB/s) and the same 16GB, so it is rarely worth the extra money for AI alone.
RTX 5060 Ti 16GB: best budget
The cheapest NVIDIA card with 16GB. Its 448 GB/s bandwidth means 14B models run at roughly 33 to 42 tokens per second in Hardware Corner’s and ComputingForGeeks’ results, which is still comfortable for chat.
Reasons to pick: lowest entry to 16GB with CUDA; 180W board power.
Reasons to skip: about 55 to 60 percent of the 5070 Ti’s speed.
The catch: avoid the 8GB version entirely for AI; it cannot hold 14B models with useful context.
RX 9070 XT: best AMD 16GB
The 9070 XT sits between the two NVIDIA cards. A llama.cpp GitHub issue records 54.3 tokens per second on Qwen3 14B at Q4_K_M with the HIP backend, and Vache Sarkissian measured 60.1 tokens per second with Vulkan on a 14B coder model.
Reasons to pick: faster than the 5060 Ti; often cheaper than the 5070 Ti.
Reasons to skip: prompt processing trails NVIDIA; the same GitHub issue documents a Vulkan slowdown on Windows with some models.
The catch: you will want Linux and some patience with backends to get the best results.
24GB tier: the enthusiast sweet spot
Twenty-four gigabytes runs 27B to 32B dense models at 4-bit with modest context, which is where local models start to feel much smarter.
Used RTX 3090: best value 24GB
Still the cheapest route to 24GB with CUDA. OpenBenchmarking.org recorded 91 tokens per second on an 8B model at Q8_0 versus 101 on the RTX 4090. Hardware Corner notes the 4090 and 5090 are 2.6 to 2.7 times faster at prompt processing, so long prompts are the 3090’s weak spot.
Reasons to pick: 24GB at a fraction of new-card pricing; two cards make 48GB for 70B models.
Reasons to skip: used-market risk; 350W draw; slow prefill.
The catch: check fan health and memory temperatures; many 3090s spent years mining.
RTX 4090: fastest 24GB
The 4090’s 1,008 GB/s makes it the fastest 24GB card, and its tensor cores keep prefill quick. It is out of production, so supply is limited to remaining stock and used cards.
Reasons to pick: strong all-round speed; widely supported.
Reasons to skip: hard to find at reasonable prices.
The catch: if pricing is close to an RTX 5090, the 5090’s extra 8GB and bandwidth are worth it.
Intel Arc Pro B60: the Linux budget pick
Intel’s workstation card offers 24GB and 456 GB/s. Sparkle launched retail 24GB blower models in January 2026, sold through Micro Center and Newegg. StorageReview’s multi-GPU preview found the hardware promising but noted that software optimization still lags. Level1Techs forum owners report llama.cpp performance improving steadily with updates.
Reasons to pick: 24GB at a low tier; blower design stacks well in multi-GPU servers.
Reasons to skip: immature software; few independent single-card benchmarks.
The catch: plan on IPEX-LLM, SYCL builds of llama.cpp or Intel’s LLM-Scaler rather than plug-and-play tools.
32GB tier: room for bigger models and long context
Thirty-two gigabytes runs 32B dense models at higher-quality quants, holds long context windows, and fits 70B models at 2-bit to 3-bit.
RTX 5090: best overall
The RTX 5090’s 1,792 GB/s is about 1.78 times the RTX 4090’s. Published llama.cpp results put it 1.5 to 1.8 times ahead of the 4090 in single-user generation. In llama.cpp discussion #19890 it generated 194 tokens per second on a 35B MoE model and read prompts at about 7,000 tokens per second. In LMSYS’s DGX Spark review, it ran gpt-oss-20b at 205 tokens per second decode, roughly four times the Spark.
Reasons to pick: the fastest consumer card for AI; 32GB covers most enthusiast models; excellent for gaming.
Reasons to skip: 575W; inflated street pricing in 2026.
The catch: a 4-bit 70B model still does not fit; for that you need two cards, a 96GB card or unified memory.
Radeon AI PRO R9700: best budget 32GB
AMD’s R9700 pairs 32GB of GDDR6 with 640 GB/s at just 300W. In discussion #19890 it reached 127.4 tokens per second on the same 35B MoE model where the 5090 hit 194.0, so the 5090 was 1.52 times faster in generation, but 2.6 to 3.4 times faster at prompt processing. The tester noted 127 tokens per second is far above the 30 to 40 tokens per second where most users stop noticing.
Reasons to pick: 32GB at a much lower tier than the 5090; low power; two cards give 64GB.
Reasons to skip: slower prefill; ROCm and Vulkan tuning required.
The catch: one owner’s write-up showed big gains only after building llama.cpp specifically for the gfx1201 target, so expect setup work.
48GB to 96GB tier: 70B and beyond on one card
RTX PRO 6000 Blackwell: best for big models
NVIDIA’s workstation flagship carries 96GB of GDDR7 with bandwidth matching the RTX 5090. LMSYS measured it at 10,108 tokens per second prefill and 215 tokens per second decode on gpt-oss-20b in Ollama. With 96GB it holds 70B models at 8-bit, gpt-oss-120b, and long contexts, all on one card with full speed.
Reasons to pick: 96GB with 5090-class bandwidth; no multi-GPU complexity.
Reasons to skip: workstation pricing far above any consumer card.
The catch: for the same spend, a Mac Studio M5 Ultra offers more memory, though with lower bandwidth and no CUDA.
Two-card setups
Two 24GB cards give 48GB, and two R9700s give 64GB. llama.cpp splits layers across cards, which works well for single-user inference. Expect the generation speed of roughly one card, not two, but you gain the capacity to run 70B models at 4-bit.
When a GPU is not the answer
If you want to run 120B-plus MoE models without workstation pricing, unified-memory systems are worth a look. NVIDIA’s DGX Spark (128GB, 273 GB/s) ran gpt-oss-120b at 58.7 tokens per second on a February 2026 llama.cpp build, and AMD’s Ryzen AI Max+ 395 mini PCs land around 49 to 54.5 tokens per second on the same model in community results. Both are much slower than a discrete GPU on models that fit in VRAM, but they hold models no consumer card can.
How to choose
- List the models you will run every day. Pick the VRAM tier from the table above, then add a few gigabytes for context.
- Within that tier, buy bandwidth. The 5070 Ti over the 5060 Ti; the 5090 over the R9700 if budget allows.
- Prefer NVIDIA if you want zero friction. CUDA works with every tool on day one.
- Choose AMD or Intel if you value capacity per dollar and run Linux.
- Check your power supply and case. A 5090 or PRO 6000 needs a 1,000W-class PSU and serious airflow.
Power, cooling and the rest of the build
The GPU is only part of a local AI machine. A few supporting choices decide whether it runs smoothly for hours:
- Power supply: 650W to 750W is enough for an RTX 5060 Ti or 5070 Ti system. An RTX 5090 or RTX PRO 6000 needs a quality 1,000W-class ATX 3.1 unit with a native 12V-2×6 cable. Two GPUs need more again.
- System RAM: match or exceed your VRAM. 32GB is a minimum, 64GB lets you offload mixture-of-experts layers to the CPU when a model is slightly too big, and 128GB opens the door to gpt-oss-120b with expert offload.
- Case airflow: inference loads can pin a GPU at full power for long periods. Mesh-front cases keep memory temperatures in check, which matters on GDDR6X and GDDR7 cards.
- Storage: models are large. A 2TB NVMe drive fills quickly once you keep several 30GB to 60GB models around.
- Multi-GPU boards: if you plan a second card, choose a motherboard with two full-length slots spaced at least three slots apart.
Setup tips
- Start with Ollama or LM Studio, then move to llama.cpp, vLLM or SGLang as needs grow.
- Use 4-bit quants by default. Step up to 5-bit or 6-bit when you have spare VRAM.
- Enable flash attention where your backend supports it to reduce KV cache memory.
- Quantize the KV cache to fit longer contexts on 16GB and 24GB cards.
- Keep drivers and llama.cpp current. Software updates regularly deliver double-digit gains.
Common mistakes
- Buying for gaming benchmarks. A card that wins in games may lose in AI if it has less VRAM.
- Choosing an 8GB card. It limits you to small models and short contexts.
- Letting models spill into system RAM. Speed can drop several times once layers leave VRAM.
- Ignoring prompt processing. For coding agents and long documents, prefill speed matters as much as generation.
Products Mentioned in This Guide
These are the specific graphics cards discussed in each VRAM tier above.
ASUS TUF Gaming GeForce RTX 5090 32GB OC Edition
As an Amazon Associate we earn from qualifying purchases at no extra cost to you.

Our best overall pick: 32GB of GDDR7 at 1,792 GB/s makes the RTX 5090 the fastest consumer card for any model that fits.
GIGABYTE GeForce RTX 5070 Ti Gaming OC 16G

The best-value 16GB card, pairing 16GB with 896 GB/s and running 14B-class models far faster than the 5060 Ti.
ASUS Dual GeForce RTX 5060 Ti 16GB OC Edition

The budget 16GB pick and the cheapest NVIDIA card with 16GB; avoid the 8GB version for local AI.
GIGABYTE Radeon RX 9070 XT Gaming OC 16G

The best AMD 16GB option, sitting between the two NVIDIA 16GB cards in generation speed, best on Linux with some backend tuning.
ASRock Radeon AI PRO R9700 Creator 32GB

The budget 32GB pick, with 640 GB/s at just 300W and about two-thirds of an RTX 5090’s generation speed.
ASRock Intel Arc Pro B60 Creator 24GB

The Linux budget route to 24GB, for users comfortable with Intel’s software stack and its still-maturing optimization.
How we compared
We compared these using manufacturer specifications, independent lab measurements from the sources named above, and owner reports. We did not bench-test these units ourselves. Figures from sites that publish bandwidth-based estimates rather than measurements were left out.
Sources
- LMSYS Org, NVIDIA DGX Spark in-depth review (RTX 5090 and RTX PRO 6000 comparison)
- llama.cpp GitHub discussion #19890, RTX 5090 vs Radeon AI PRO R9700
- llama.cpp GitHub discussion #16578, DGX Spark performance
- llama.cpp GitHub issue tracker, RX 9070 XT results
- OpenBenchmarking.org, llama.cpp results
- Hardware Corner, GPU ranking for local LLMs
- ComputingForGeeks, RTX 5060 Ti vs RTX 5070 Ti for local AI
- Vache Sarkissian, Vulkan vs ROCm on RDNA 4
- StorageReview, Intel Arc Pro B60 Battlematrix preview
- TechPowerUp, Sparkle Arc Pro B60 launch
- Level1Techs forums, Arc Pro B60 for local LLMs
- Puget Systems, Radeon AI PRO R9700 dual-GPU inference
- AIMultiple, DGX Spark alternatives
Check your own setup: our LLM VRAM calculator estimates how much memory a model needs at each quantization and context length, and shows which GPUs and Macs it fits.
Frequently Asked Questions
How much VRAM do I need to run a local LLM?
About 8GB to 12GB for 7B to 8B models, 16GB for 14B models and gpt-oss-20b, 24GB to 32GB for 27B to 32B models, and 48GB or more for 70B at 4-bit.
Is NVIDIA better than AMD for local AI?
NVIDIA has the smoothest software support and faster prompt processing. AMD offers more VRAM per dollar, especially with the 32GB R9700, but expect more setup work.
Is the RTX 5090 worth it for local LLMs?
If you need 32GB and the fastest speed, yes. If your models fit in 16GB, an RTX 5070 Ti delivers most of the experience for far less.
Can I use two GPUs for one model?
Yes. llama.cpp, vLLM and others split models across GPUs. You gain capacity; generation speed stays closer to a single card for one user.
Is a used RTX 3090 still worth buying in 2026?
For 24GB on a budget, yes. It generates text at a decent pace but reads long prompts much slower than newer cards.
What about the RTX 5080 for AI?
It has the same 16GB as the 5070 Ti with slightly more bandwidth, so it is only marginally faster for local LLMs. The 5070 Ti is the better value for AI.
Do I need a workstation card like the RTX PRO 6000?
Only if you need 70B-plus models on a single card at full speed. For most home users, a 32GB consumer card or a unified-memory system is more practical.
Ready to decide? Our #1 pick for 2026 is the 7B to 8B.
Live price & availability on Amazon.



Write Your Review
No reviews yet. Be the first to share your experience!