
If you are buying a GeForce RTX card specifically for machine learning, forget boost clocks and RGB. What matters is VRAM capacity, memory bandwidth, Tensor core throughput, and whether the card will actually run for 12 hours straight without throttling or crashing. NVIDIA owns this space because of CUDA, cuDNN, and mature PyTorch support, so even a midrange RTX will be easier to set up than a faster card from a competitor.
For most people learning ML at home, fine-tuning small LLMs, training Stable Diffusion LoRAs, or running computer vision projects, you do not need the flagship. You need enough VRAM to load your model plus optimizer states plus a usable batch size, and enough cooling to sustain it.
What actually matters for ML
VRAM is the hard limit. If your model does not fit, it does not train. System RAM cannot substitute without a massive speed penalty. As a rough rule: 8GB is enough for learning PyTorch, small CNNs, and inference with 7B quantized LLMs. 12GB lets you fine-tune Stable Diffusion and train most vision models comfortably. 16GB is the current sweet spot for 7B-13B LLM fine-tuning with QLoRA and for SDXL. 24GB opens up full fine-tuning of 7B models and much larger batch sizes.
Second is compute: Tensor cores, FP16/BF16 and INT8 performance. All RTX 40-series cards have excellent Tensor cores and support FP8, which helps with newer frameworks. The difference between models is mostly speed, not compatibility. A cheaper card will run the same code, just slower.
Third is sustained thermals and power. ML is not gaming. Gaming spikes the GPU for seconds. Training pins it at 95-100% for hours. Dual-fan cards in a cramped case will throttle, and blower vs. open-air matters if you ever plan to run two GPUs side-by-side. Check your PSU wattage, 12VHPWR cable, and case clearance before you buy, especially for the 350W+ cards.
Quick comparison
In practice, most buyers are choosing between these four tiers. Prices fluctuate, but the VRAM differences do not:
| Card Tier | VRAM | Best For | Main Trade-off |
|---|---|---|---|
| RTX 4060 Ti 16GB | 16GB GDDR6 | Learning, QLoRA, Stable Diffusion LoRA on a budget | Narrow 128-bit bus, slower training |
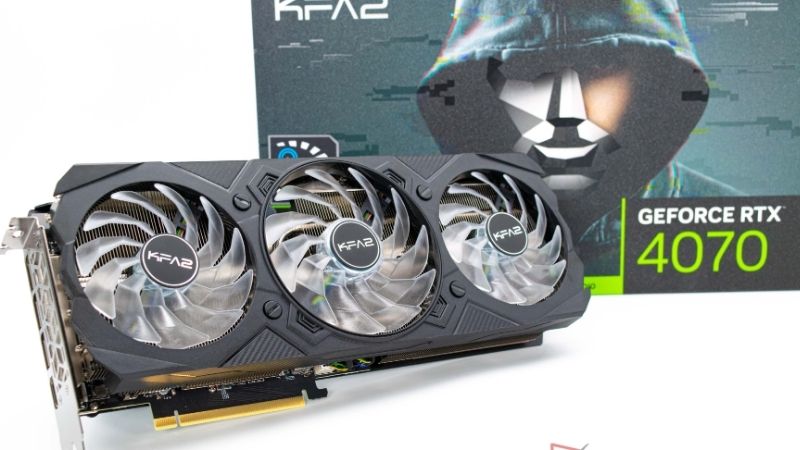
| RTX 4070 Super / 4070 Ti Super | 12GB / 16GB GDDR6X | Best balance for vision, SDXL, 7B LLMs | 12GB version can feel tight for LLMs |
| RTX 4080 Super | 16GB GDDR6X | Faster iteration, larger batches | Price premium over 4070 Ti Super for same VRAM |
| RTX 4090 | 24GB GDDR6X | Serious local LLM work, SDXL full tuning | Huge, power-hungry, expensive |
Best overall: RTX 4090 24GB
If budget is not the constraint and you want to train locally rather than rent cloud GPUs, the RTX 4090 is still the only GeForce card with 24GB of VRAM. That extra 8GB over every other option is transformative. You can full fine-tune a 7B LLM in FP16 with the right optimizer setup, train SDXL without constant offloading, and run 13B models in 8-bit for experimentation without dropping to CPU.
It is also roughly 1.5x to 1.8x faster than a 4070 Ti Super in training throughput, which matters when an experiment takes 9 hours instead of 14. Failure modes are physical, not software: it needs a 850W+ quality PSU, four slots of clearance in many AIB versions, and good case airflow. I have seen more stability issues from underpowered PSUs and daisy-chained PCIe cables than from drivers. Use the native 12VHPWR cable, undervolt or set an 80-90% power limit if your room gets hot, and temperatures stay manageable.
Who it suits: someone doing daily training, freelancing with generative AI, or trying to avoid $200/month in cloud bills. Who should skip it: students following tutorials. You will not learn PyTorch faster on a $1,800 card.
Best value for most: RTX 4070 Ti Super 16GB
For most buyers, 16GB is enough and the RTX 4070 Ti Super 16GB hits the sweet spot. You get the same VRAM capacity as the 4080 Super for usually several hundred dollars less, with about 85% of the speed. In real terms, that means QLoRA fine-tuning of Llama 2 7B / Mistral 7B with 4-bit quantization works fine, Stable Diffusion 1.5 LoRA training is comfortable, and SDXL LoRA is doable if you use gradient checkpointing, xFormers, and batch size 1-2.
Trade-off: memory bandwidth is lower than the 4080 Super and 4090, so data-heavy vision training and large-batch work will be slower. Some 4070 Ti Super models also have smaller coolers that get loud under sustained load. Look for a triple-fan version if your PC sits on your desk.
Get the 16GB Ti Super specifically, not the base 4070 Super 12GB, if LLMs are your focus. That 4GB difference decides whether a 7B QLoRA run fits comfortably or needs aggressive offloading that kills speed.
Budget pick that is still useful: RTX 4060 Ti 16GB
The RTX 4060 Ti 16GB is slow for its price in gaming, but for ML the logic flips: it is the cheapest new GeForce card with 16GB. If your alternative is an 8GB or 12GB card, the slower 4060 Ti will still run models the faster cards cannot load at all.
Expect longer training times. Its 128-bit memory bus limits bandwidth to around 288 GB/s, less than half a 4090. SDXL training will work but feel sluggish, and full fine-tuning is out of reach. Where it shines is learning, inference, dataset prep, and QLoRA experiments where you care more about iteration than throughput. It also sips power at 160W, so it runs cool and fits in almost any system with a 550W PSU.
Failure mode to know: do not buy the 8GB version by mistake to save $80. Listings mix them together. For ML, the 8GB 4060 Ti is a dead end. The entire point of this card is the 16GB variant.
When the cheaper option is fine
Be honest about your workload. If you are taking a Coursera PyTorch course, doing Kaggle tabular competitions, training ResNet or YOLO on 256×256 images, or just running Ollama / llama.cpp for chat, even a used RTX 3060 12GB or new RTX 4070 12GB is fine. CUDA compatibility is the same, and batch sizes stay small while you learn.
Renting is also cheaper if you only train occasionally. A $60 cloud run twice a month is $1,440 per year, less than a 4090, with no heat or PSU worries. Buying makes sense when you train weekly, work with private data you cannot upload, or need low-latency inference for apps and Stable Diffusion.
Avoid SLI/NVLink thinking. GeForce cards no longer pool VRAM for training like that. Two 12GB cards do not equal 24GB in PyTorch without complex model parallelism most beginners should not attempt. One card with more VRAM beats two smaller cards almost every time.
Setup tips that prevent headaches
Use Linux if you can. Ubuntu 22.04 with the proprietary NVIDIA driver, CUDA 12.x, and PyTorch installed via pip has far fewer issues than Windows for LLM libraries like bitsandbytes, FlashAttention, and TRL. If you stay on Windows, use WSL2.
Plan for 32GB system RAM minimum, 64GB if you work with large datasets. Keep at least 30GB free on a fast NVMe SSD for datasets, checkpoints, and Hugging Face cache, which balloons quickly. And set your training script to save checkpoints often. Consumer cards lack ECC VRAM, and a power blip or overheat 10 hours into a run without checkpoints means starting over.
FAQ
How much VRAM do I need for machine learning?
12GB is the practical minimum for comfortable work in 2026, 16GB is the sweet spot for LLMs with QLoRA and Stable Diffusion XL, and 24GB is worth it only if you fine-tune often or train with larger batches. When in doubt, buy more VRAM over more raw speed.
Is the RTX 4090 overkill for beginners?
Yes, for learning. You can learn all the fundamentals on a 12GB or 16GB card. Buy the 4090 if you are training regularly and cloud costs or data privacy push you to local training, not to learn faster.
Can I use GeForce instead of professional RTX 6000 Ada cards?
For most independent developers and students, yes. GeForce supports CUDA, cuDNN, PyTorch, TensorRT-LLM, and Stable Diffusion tooling. Professional cards offer 48GB VRAM, ECC, and better multi-GPU support, but cost 4-5x more for similar speed.
Will an RTX card work in my existing PC for ML?
Usually, if your PSU and case fit. A 4060 Ti 16GB works in most systems with a 550W PSU. A 4070 Ti Super / 4080 Super wants 750W-850W, and a 4090 wants 850W-1000W with a native 12VHPWR cable. Measure GPU length and check airflow first — sustained ML loads run hotter than gaming.

Write Your Review
No reviews yet. Be the first to share your experience!